MMM
- Overview
- Models
- Workflow
- Methodology
- Results
MMM: Overview
Introduction
Naukr AI MMM is a Bayesian, panel-aware system for estimating how media and non-media business drivers contribute to an observed business outcome over time. A model can use a national time series or a time-by-geography panel and can represent media at any resolved node level, such as channel, vehicle, campaign, or creative, provided the ingestion layer maps those nodes to parent pooling groups.
The model addresses four related questions:
- How much of the outcome is attributable to baseline demand, controls, and media?
- How does media effectiveness change after carryover and diminishing returns?
- What is the posterior uncertainty around contribution and ROI?
- Is the attribution supported by the data, sampler diagnostics, holdout performance, and prior-sensitivity checks?
The core modeling philosophy is:
- represent the temporal memory and nonlinear response of media explicitly;
- preserve business meaning through outcome-specific conversion and ROI logic;
- use partial pooling when individual media nodes or geographies are weakly identified;
- propagate uncertainty through parameters, predictions, contributions, and ROI;
- select discrete model families outside NUTS using leakage-safe validation;
- separate model estimation from the decision to publish production outputs.
Model architecture at a glance
Client data
  -> schema and semantic validation
  -> canonical time x geography panel
  -> train-only scaling and feature preparation
  -> adstock/carryover by media node
  -> saturation by media node or parent group
  -> optional constrained neural response correction
  -> additive or multiplicative Bayesian outcome model
  -> NumPyro NUTS posterior sampling
  -> posterior prediction and counterfactual reconstruction
  -> contribution, ROI, response-curve, and diagnostic artifacts
  -> quality decision
  -> optional approved all-history production refit
  -> later-stage budget optimization
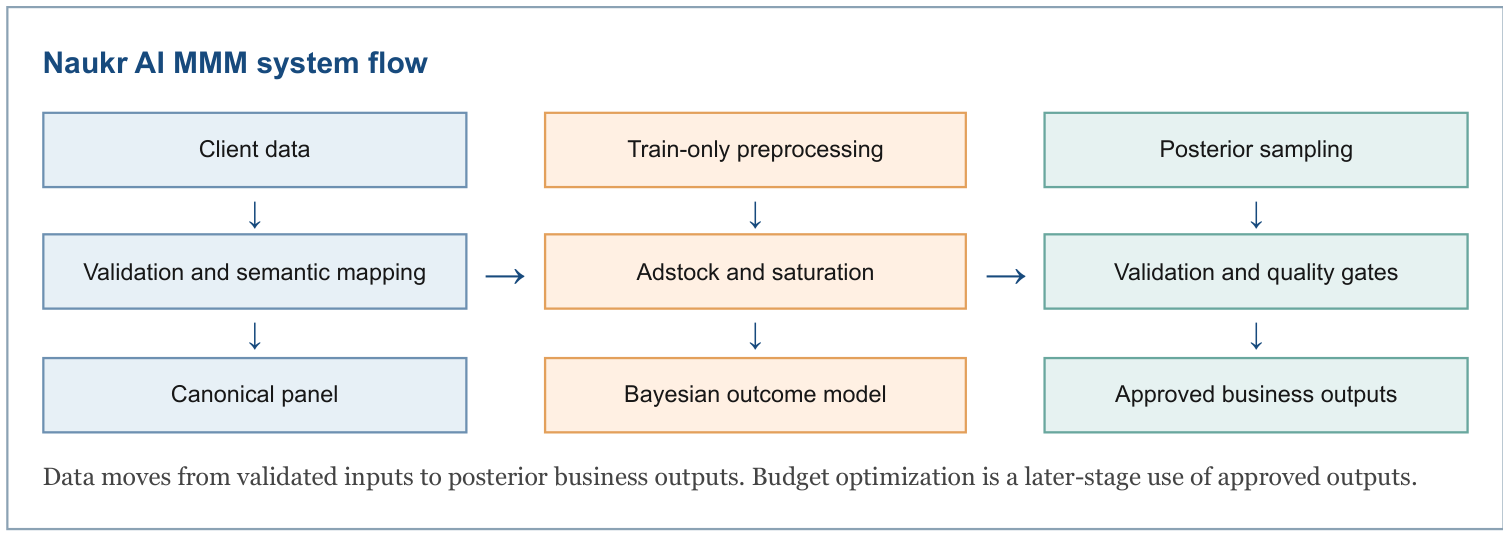
At a high level, the expected outcome contains:
- a baseline: global intercept, geography offsets, trend, and optional baseline dynamics and seasonality;
- controls: standardized non-media variables with estimated coefficients;
- media effects: scaled exposure passed through adstock, saturation, and an optional shape-constrained neural correction;
- observation noise: Student-t for the additive form or LogNormal, optionally contaminated, for the multiplicative form.
Current capability boundary
| Capability | Current implementation |
|---|---|
| Additive model | Supported and the default |
| Multiplicative log-link model | Supported when the outcome is strictly positive |
| Geometric adstock | Supported |
| Weibull adstock | Supported |
| Weibull-CDF saturation | Supported and the default |
| Anchored logistic saturation | Supported |
| Constrained neural response correction | Supported and configurable |
| Geography random intercepts | Supported |
| Media node to parent-group pooling | Supported |
| Weibull response-curve export | Supported |
| Budget optimization | Included as a later-stage workflow after approved model outputs |
Related documentation
- Models — notation, baseline, adstock, saturation, neural layer, additive vs multiplicative form (
mmm-models) - Workflow — the 15-step end-to-end model flow (
mmm-workflow) - Methodology — priors, NUTS inference, likelihood, diagnostics, identifiability (
mmm-methodology) - Results — posterior contributions, ROI, and uncertainty summaries (
mmm-results)
MMM: Models
Notation and core mathematical specification
Let:
- index time;
- index geography;
- index a resolved media node;
- map media node to a parent pooling group;
- index a control variable;
- be the modeled outcome;
- be raw media execution or exposure;
- be media spend;
- be a control value;
- be profit or business value per modeled KPI unit;
- be the observation mask.
Leakage-safe preprocessing
For media node , the exposure scale is the median positive exposure in the fitting data:
Typical media exposure equals the middle positive exposure in the fitting data. Scaled exposure equals raw exposure divided by that typical exposure.
Terms: is the typical positive exposure for media node ; is raw exposure at time , geography , and media node ; marks observations included in fitting; is scaled exposure.
Controls use fitting-period means and standard deviations:
Standardized control equals the control value minus its fitting-period average, divided by its fitting-period standard deviation.
Terms: is the standardized control; is the raw control value; is its fitting-period mean; is its fitting-period standard deviation; identifies the control.
The additive outcome is standardized with fitting-period location and scale :
Standardized outcome equals the observed outcome minus its fitting-period average, divided by its fitting-period standard deviation.
Terms: is the standardized outcome; is the observed outcome; is the fitting-period mean outcome; is its fitting-period standard deviation.
All preprocessing statistics are learned only from the active fitting mask. A final evaluation refit uses train plus validation and continues to exclude the locked test. An approved production refit can use all available history.
Baseline predictor
The shared scaled baseline is
Baseline demand equals the overall level plus geography and time effects plus the combined effects of all controls.
Terms: is scaled baseline demand; is the global intercept; is the geography offset; is the time-related baseline effect; is control 's coefficient; is its standardized value; is the number of controls.
where is the global intercept, is a partially pooled geography offset, is the selected trend, seasonality, or dynamic baseline contribution, and is a control coefficient.
Transformed media response
For each media node, the model constructs
Transformed media response equals scaled exposure after carryover, diminishing returns, and any approved constrained correction.
Terms: is the transformed media response; is the adstock or carryover function; is the saturation function; is the identity or constrained neural correction; maps node to its parent group; is the scaled exposure history.
where is adstock, is saturation, and is either the identity mapping or the constrained neural correction. Parameters may be fixed or estimated and can be scoped to each media node or its parent group as allowed by the specification.
Additive outcome model
The expected outcome in original modeled-KPI units is
Expected outcome equals restored baseline demand plus the contribution from every media node.
Terms: is the expected outcome; restores the baseline to outcome units; is media node 's effect coefficient; is the transformed response; is the number of media nodes.
Equivalently, on the standardized likelihood scale:
Standardized expected outcome equals scaled baseline plus media contributions expressed in standardized outcome units.
Terms: is the standardized expected outcome; is the scaled baseline; is the outcome standard deviation; is media node 's contribution in outcome units.
Media contributions add exactly to total media lift:
A node's contribution equals its effect times its transformed response. Total media lift is the sum of all node contributions.
Terms: is the contribution from media node ; is its effect coefficient; is its transformed response; is the total media contribution.
Multiplicative log-link outcome model
The multiplicative form requires positive fitting outcomes. It builds a business baseline on the log scale:
Log baseline equals the restored scaled baseline. A media node's log lift equals its effect times its transformed response.
Terms: is the log baseline; and are the fitting-period mean and standard deviation of the log outcome; is the scaled baseline; is node 's log lift; and are its effect and transformed response.
Total expected log outcome equals log baseline plus all media log lifts.
Terms: is the total expected log outcome; is the log baseline; is media node 's log lift.
With ordinary LogNormal noise, the response-scale posterior mean is
Expected outcome equals the exponentiated log prediction with a correction for log-scale noise.
Terms: is the expected outcome given model parameters ; is the expected log outcome; is the log-scale observation noise.
Thus media acts as a positive proportional lift over a baseline rather than as an additive number of outcome units.
Media response modeling
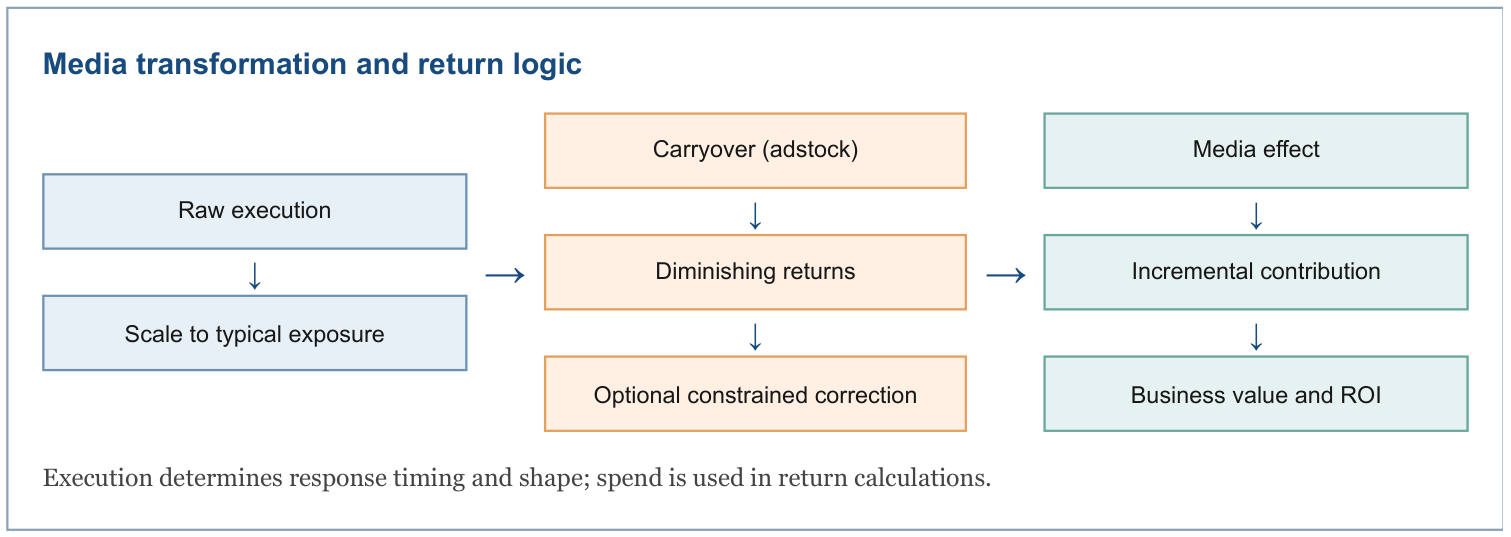
The model never applies a coefficient directly to raw spend. Raw execution is first scaled, carried through time, and saturated. A media coefficient therefore operates on transformed media pressure.
The pipeline for node is:
- scale execution by its train-only typical positive level;
- apply a causal finite-lag adstock kernel;
- apply a bounded, zero-anchored saturation curve;
- optionally blend the curve with a monotone, concave neural response;
- multiply by an additive outcome-unit coefficient or a multiplicative log-effect coefficient.
Execution and spend have distinct roles. Execution identifies response shape and timing; spend is the denominator in ROI and, in the additive form, participates in the business-scale ROI parameterization.
Adstock, retention, and half-life
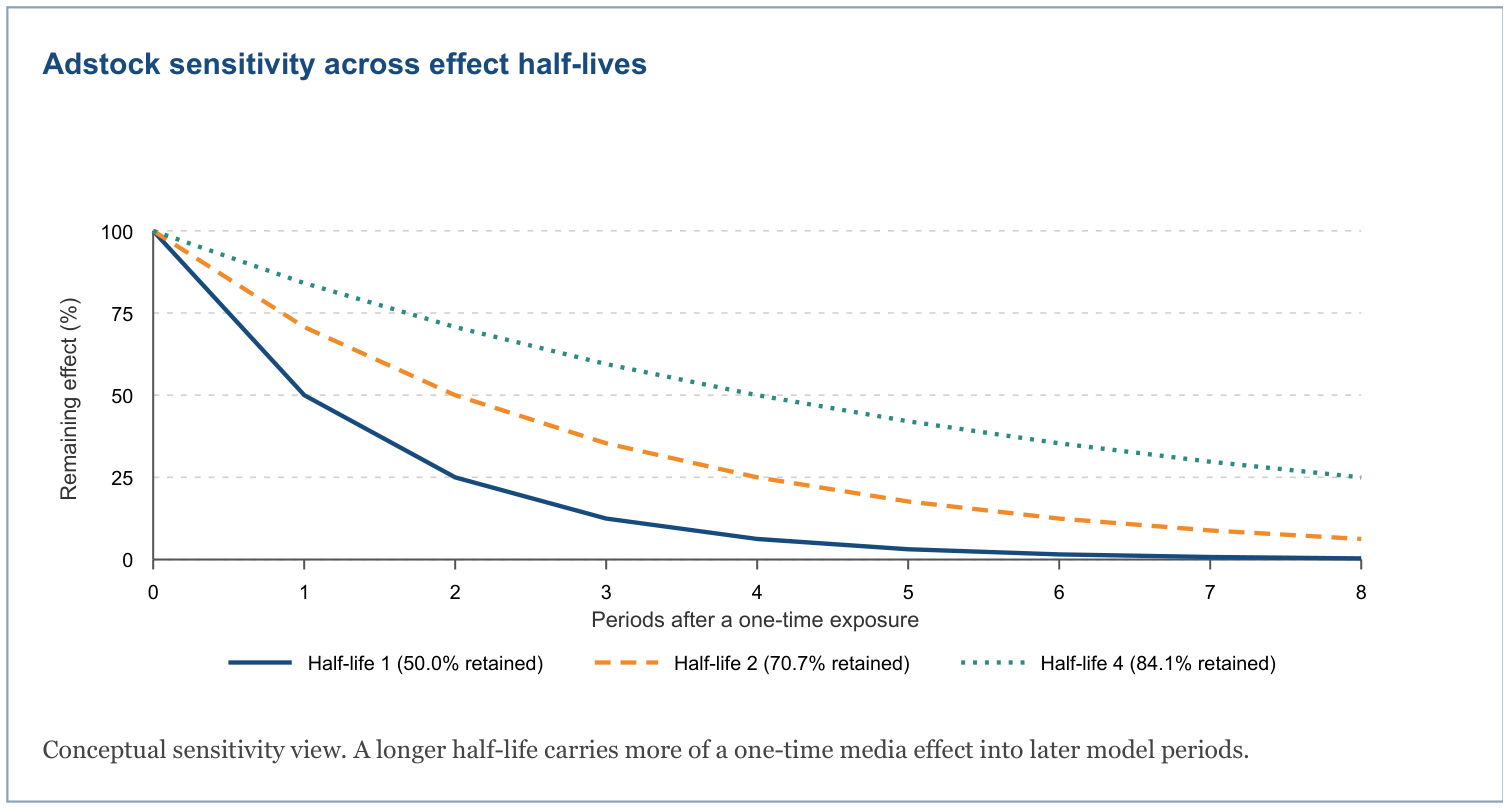
Adstock encodes the fact that media pressure can persist after execution.
Geometric adstock
For retention and maximum lag , normalized weights are
Each lag receives a decaying carryover weight, and all lag weights are divided by their total so they sum to one.
Terms: is media node 's weight at lag ; is retention; is the maximum lag; indexes all included lags.
The carried exposure is
Adstocked exposure is the weighted sum of current and previous scaled exposures.
Terms: is adstocked exposure; is the weight at lag ; is scaled exposure periods earlier.
with unavailable pre-history treated as zero. Normalization keeps a constant input on a comparable scale across retention settings.
The half-life , in model periods, is related to retention by
Retention is chosen so that the remaining media effect falls to one half after the stated half-life.
Terms: is per-period retention for media node ; is its effect half-life measured in model periods.
with when the configured half-life is zero. Retention can also be configured directly; a direct retention specification takes precedence.
Weibull adstock
Weibull adstock supports a delayed peak. For shape and scale , define survival at lag as
Remaining carryover at a lag is an exponential decay whose timing is controlled by Weibull scale and shape.
Terms: is the remaining carryover at lag ; is Weibull shape; is Weibull scale; identifies the media node.
Unnormalized lag mass is
The effect assigned to a lag equals the drop in remaining carryover from that lag to the next.
Terms: is unnormalized effect mass at lag ; and are remaining carryover at consecutive lags.
and the finite-lag weights normalize over . The same causal convolution used for geometric adstock then produces .
Configuration and estimation
The default maximum lag is 8 periods. Adstock parameters can be fixed or given priors, and can be estimated at media-node or parent-group scope. Default prior settings include a 2-period geometric half-life median, Weibull shape median 1.5, and Weibull scale median 3. These are prior centers, not hard-coded fitted values.
Saturation and diminishing returns
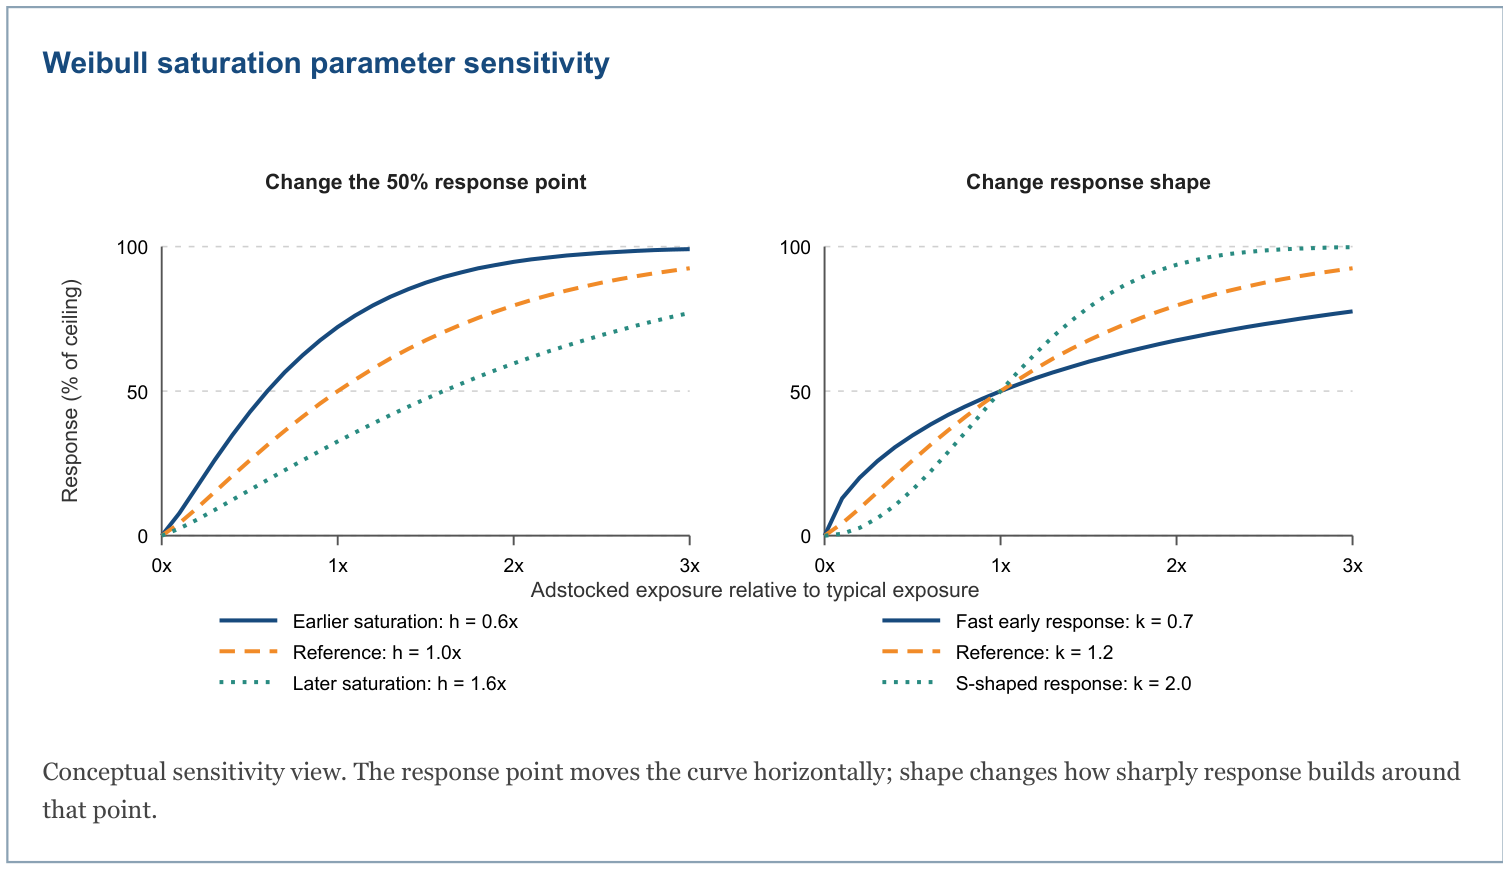
Saturation maps non-negative adstocked pressure to a bounded response. Every implemented family starts at zero. The discrete family is selected in the model specification and compared across candidates outside NUTS.
Weibull-CDF saturation
The default is
Saturated response equals one minus the remaining unrealized response; exposure is measured relative to the half-response point and curved by the shape parameter.
Terms: is the response between zero and one; is adstocked exposure; is the 50% response point; controls curve shape; prevents negative exposure.
where is exactly the 50% response point and controls shape:
At exposure equal to the half-response point, the modeled response is exactly 50% of its ceiling.
Terms: is the saturated response; is the 50% response exposure; is the curve-shape parameter; 0.5 means half of maximum response.
The default prior medians are typical exposure and .
Anchored logistic saturation
Let midpoint , slope , and
The anchor value is the ordinary logistic response at zero exposure.
Terms: is the zero-exposure anchor; is the logistic midpoint; is the slope; is the exponential function.
The zero-anchored logistic response is
Start with the logistic response, subtract its zero-exposure value, and rescale it so response begins at zero and approaches one.
Terms: is the zero-anchored response; is adstocked exposure; is the midpoint; is the slope; is the zero-exposure anchor.
Subtracting and rescaling by makes .
Constrained neural response layer
The neural component is a small shape-constrained correction to the parametric saturation response. It is not an unrestricted residual network and does not bypass the Bayesian model.
Let be the selected parametric saturation response for a parent media group. For neural unit , define
Each neural basis converts the parametric response into a smooth increasing curve that starts at zero and is normalized to one.
Terms: is the basis-unit response; is the parametric saturation response; is the unit bias; is a positive unit slope; softplus is a smooth positive transformation.
where . Each basis is zero-anchored, normalized at one, monotone, and concave. The neural curve is
The neural curve is a weighted average of all basis curves, with positive weights that sum to one.
Terms: is the combined neural curve; is the number of units; is unit 's basis response; is its normalized weight; is the raw weight vector.
The final transformed response is a shrinkage blend:
Final response blends the original parametric curve with the neural correction; the blend weight controls how much correction is allowed.
Terms: is the final corrected response; is the original parametric response; is the neural curve; is the blend weight from zero to one.
The default has two units and , strongly favoring the parametric curve unless the likelihood supports a correction. Weight logits and raw slopes use Normal(0, 0.5) priors; biases use Normal(0, 1). One weight logit is fixed as a reference for identifiability.
All non-fixed neural parameters are sampled jointly by NUTS. Their posterior uncertainty therefore propagates into media response, contributions, ROI, and predictions. Setting use_neural_correction=False makes .
Additive versus multiplicative specification
| Property | Additive | Multiplicative log-link |
|---|---|---|
| Outcome support | Real-valued outcome scale | Strictly positive fitting outcome |
| Media effect | Outcome-unit increment | Positive proportional lift |
| Likelihood | Student-t on standardized outcome | LogNormal or contaminated LogNormal |
| Primary media prior | Business-scale ROI | Positive transformed-media coefficient |
| Node contribution | Full prediction minus channel-removal counterfactual | |
| Decomposition additivity | Exact | Requires separate conserving allocation |
| Baseline dependence | Same absolute lift at same response | Lift grows with baseline level |
Multiplicative counterfactual contribution
Let
Full prediction is the model's expected outcome with all variables included.
Terms: is the full expected prediction; is the outcome; represents all fitted model parameters.
and let be the expected prediction after removing while holding all other posterior values fixed. Then
A media node's removal contribution is full prediction minus the prediction with that node removed.
Terms: is the counterfactual contribution; is the full prediction; is the prediction with media node removed.
Individual removal effects overlap under a log link, so they do not sum exactly to the total lift. For decomposition charts, the implementation also emits a conserving allocation:
Total media lift is divided among nodes in proportion to each node's log lift so allocated contributions add back to total lift.
Terms: is the conserving allocated contribution; is the full prediction; is the baseline-only prediction; is node 's log lift; indexes all media nodes.
with a safe zero-effect convention. Counterfactual contribution is used for causal removal and ROI interpretation; conserving contribution is used where components must reconcile exactly to the predicted total.
Model form is an explicit candidate choice. Eligibility checks prevent use of the multiplicative form when its positive-outcome assumptions are not met.
Controls, external variables, and baseline
Controls are generic numeric variables supplied by the client. Price, promotion, distribution, holidays, macroeconomic factors, competitor activity, and supply variables are supported when they are mapped to controls at the model's time and geography grain. The model does not infer business semantics from the coefficient alone; semantic classification occurs during ingestion.
Baseline families
- Linear: global intercept, centered geography offset, and linear trend.
- Piecewise linear: linear trend plus equally spaced hinge bases. Hinge features are orthogonalized against intercept and trend and standardized on fitting periods.
- Recent level: adds an indicator beginning at a configured fraction of the fitting window.
- Dynamic AR(1): adds a recursively evolving latent state with bounded persistence and estimated innovation scale. The state is centered on fitting periods.
- Local linear trend: recursively evolves level and slope innovations and orthogonalizes the result against intercept and linear trend.
Optional Fourier seasonality adds sine and cosine terms. The default seasonal period is 52 and the default number of harmonics is zero, so seasonality is enabled only when requested by the selected specification.
Holiday flags and similar controls are not special likelihood terms. They enter through standardized control columns. For additive models their effects are outcome-unit components after reversing target scaling. For multiplicative models they modify the log baseline and are reported through response-scale counterfactual removal.
Hierarchical and multi-level modeling
The implementation uses two distinct hierarchies.
Geography baseline hierarchy
For , raw geography offsets use a non-centered parameterization:
Each geography starts with a standard-normal raw deviation, while a separate positive scale controls how different geographies may be.
Terms: is geography 's raw deviation; is the common geography variation scale; 0 and 1 are the standard-normal mean and scale; 0.5 is the prior scale for geography variation.
Final geography effect equals the common variation scale times that geography's raw deviation after removing the average raw deviation.
Terms: is the centered geography effect; is the geography variation scale; is the raw geography deviation; is the number of geographies; indexes all geographies.
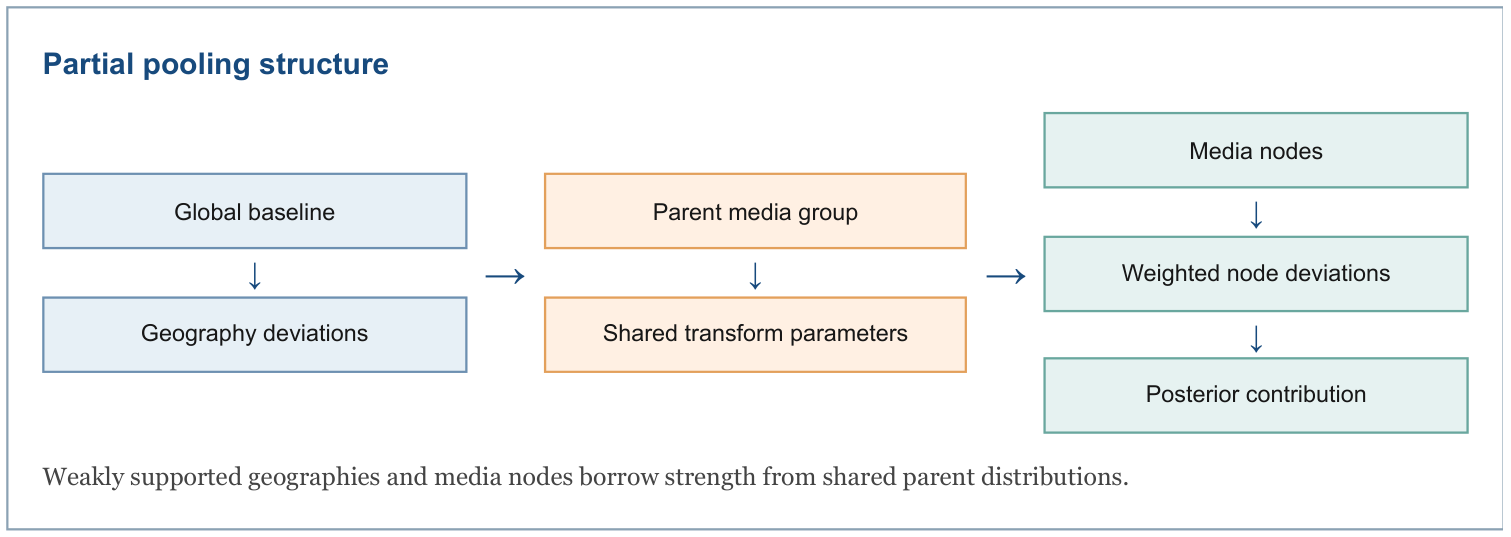
One raw reference element is fixed before centering. This separates the global level from geography deviations and partially pools low-information regions. For a single geography, the deviation is zero.
Media-node hierarchy
The model is dimension-name agnostic. A media node may represent a channel, vehicle, campaign, creative, or another ingested entity. Every node maps to a parent pooling group. Transform parameters may be shared at parent-group scope or estimated at media-node scope. Media effects use group shifts plus weighted node deviations.
An identification analysis assigns each node one of these operational states:
- individually estimable;
- estimable with partial pooling;
- group only;
- unsupported.
The analysis uses active-period coverage, number of active periods, coefficient of variation, unique positive values, pairwise correlation, variance inflation factor, and spend support. Default warning thresholds include 5% active fraction, 6 active periods, 0.05 coefficient of variation, 0.95 pairwise correlation, VIF 10, and 3 unique positive values. Pooling begins earlier at correlation 0.80 or VIF 5 and can reduce the node deviation weight as low as 0.25 before moving to group-only attribution.
Product, retailer, or other business dimensions are supported when ingestion represents them in the canonical panel or media-node mapping. They are not separate hard-coded latent axes in the current model.
MMM: Workflow
Model lifecycle
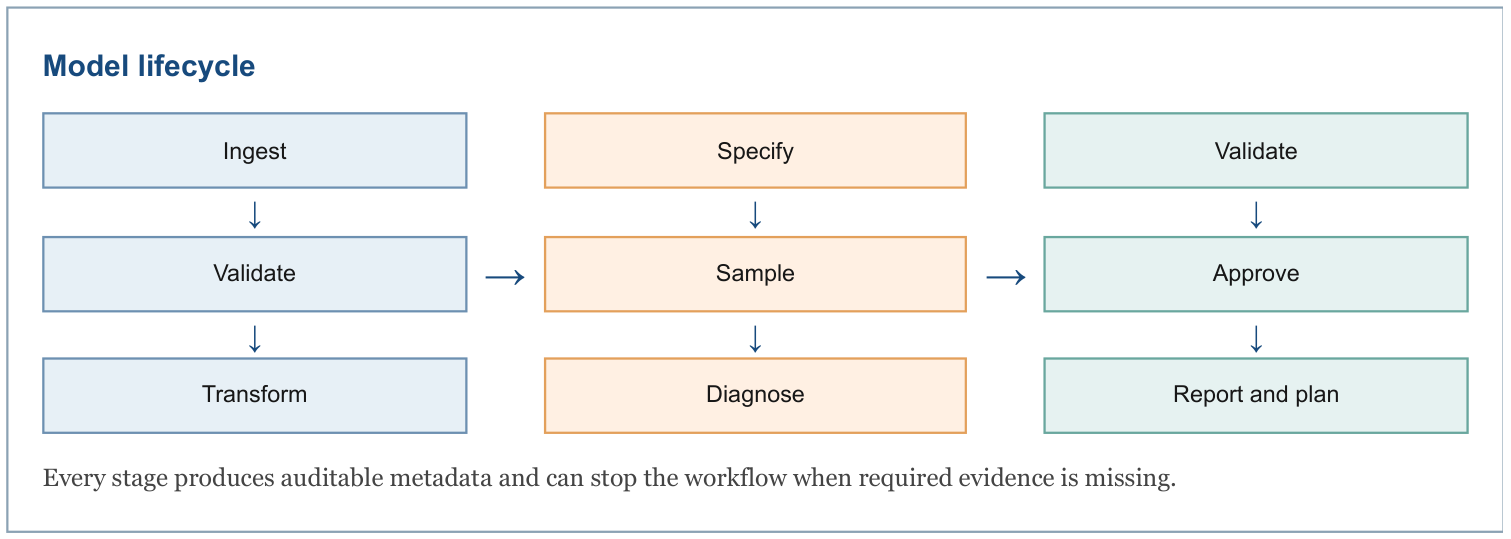
End-to-end model flow
Step 1: Ingest and classify data
Client outcome, media, spend, geography, time, control, and business-value data are mapped to a canonical schema. Ingestion validates required fields, numeric values, time grain, geography grain, media hierarchy, and semantic roles.
Step 2: Build the canonical panel
The adapter constructs aligned arrays for target , media , controls , spend , observation mask , media-to-group mapping, and business-value multipliers.
Step 3: Validate contracts and source readiness
Contracts enforce finite values, non-negative media and spend, positive business scales, contiguous group indexes, and coherent zero-spend behavior. Optional source-readiness rules validate semantic driver coverage, timestamp alignment, time grain, evidence sources, and reviewed material events.
Step 4: Diagnose identification and set adaptive pooling
The model measures activity, variation, spend support, correlations, and VIF. It converts this evidence into node-level pooling weights and attribution statuses.
Step 5: Create leakage-safe evaluation splits
The orchestration layer creates chronological train, validation, and locked-test masks, plus optional rolling-origin and balanced geography-time folds.
Step 6: Fit preprocessing on the active training mask
Exposure scales, control means and standard deviations, outcome location and scale, trend features, and baseline bases are estimated only from fitting data.
Step 7: Transform media
For every node, scaled exposure passes through the selected geometric or Weibull adstock, selected saturation family, and optional constrained neural correction.
Step 8: Construct the Bayesian model
The selected baseline, hierarchy, controls, media effects, and likelihood are assembled as an additive or multiplicative NumPyro model.
Step 9: Sample the posterior
NUTS performs warm-up and posterior sampling. JAX provides automatic differentiation, compilation, and available accelerator execution.
Step 10: Evaluate candidates
Posterior predictions are evaluated on validation and rolling folds. Sampling, predictive, peak-capture, interval, reconciliation, and identification gates are applied. Discrete candidates are ranked only after passing the configured gates.
Step 11: Refit the selected specification for locked testing
The selected model is refit on train plus validation using preprocessing learned without the test window. The locked test is used once for final evaluation.
Step 12: Test prior sensitivity and publication readiness
The active media prior is widened and attribution shares are compared. Quality flags combine sampling, predictive, source, identification, reconciliation, and sensitivity evidence.
Step 13: Produce posterior business artifacts
The reporting layer writes time-level contributions, grouped and yearly ROI, baseline/control/media decomposition, response curves where supported, prior-posterior diagnostics, holdout diagnostics, quality flags, and platform adapters. Each artifact retains uncertainty intervals and attribution metadata.
Step 14: Optional approved production refit
After an external quality decision marks the model ready and sensitivity results exist, the selected specification may be refit on all approved history. This refit does not replace the locked-test evidence; it produces the production posterior used by reporting, planning, and later-stage budget optimization.
Step 15: Later-stage budget optimization
Approved posterior response curves, contribution estimates, ROI distributions, uncertainty, and business constraints feed the budget-optimization stage. This stage evaluates allocation scenarios only after model estimation, validation, and publication-readiness checks are complete.
For the estimation and validation details behind steps 8–12, see mmm-methodology.
For the outputs produced in step 13, see mmm-results.
MMM: Methodology
Priors and Bayesian parameterization
Priors regularize weakly identified MMM components and provide a formal place for defensible business evidence. Defaults can be replaced with fixed values or reviewed custom priors through the model specification.
Positive and bounded parameters
Positive transform parameters use
A positive parameter is given a log-normal prior centered on the chosen median with stated log-scale uncertainty.
Terms: is a positive model parameter; is its prior median; is prior uncertainty on the log scale; means "modeled as distributed according to."
where is the prior median. Probabilities such as retention and neural blend weights use Beta priors. These parameterizations enforce valid domains without post-sampling clipping.
Baseline and control priors
| Parameter | Default prior or scale |
|---|---|
| Global intercept | Normal(0, 1) |
| Geography scale | HalfNormal(0.5) |
| Geography raw offsets | Normal(0, 1), centered |
| Linear trend coefficient | Normal(0, 0.25) |
| Control coefficients | Normal(0, 0.25) |
| Piecewise trend-change raw coefficients | Normal(0, 1), multiplied by 0.10 |
| Recent-level raw coefficient | Normal(0, 1), multiplied by 0.25 |
| Dynamic AR persistence | 0.95 x Beta(4, 2) |
| Dynamic AR innovation scale | HalfNormal(0.05) |
| Local-level innovation scale | HalfNormal(0.04) |
| Local-slope innovation scale | HalfNormal(0.01) |
| Seasonal coefficients | Normal(0, 1), multiplied by 0.10 |
Additive ROI hierarchy
The additive model uses a business-scale ROI prior for every media node. If and are the submitted log-prior location and scale, then
A node's log ROI equals its submitted prior center plus its parent-group shift plus a scaled node-specific deviation.
Terms: is ROI for media node ; is the submitted log-prior center; is the parent-group shift; is the submitted prior uncertainty; is the node deviation.
The parent-group shifts are centered and use a default scale of 0.15. The node deviations are non-centered, shrunk, and weighted by the adaptive pooling plan. A group-only node receives no unsupported unique deviation.
The coefficient is derived from ROI rather than sampled independently:
First total the business-valued transformed response. Then choose the effect coefficient so modeled profit contribution divided by spend equals the sampled ROI.
Terms: is total business-valued response support; is the fitting mask; is the transformed response; is business value per outcome unit; is the effect coefficient; is node ROI; is fitting-period spend; is a small positive safeguard against division by zero.
where is fitting-period spend. This guarantees ROI reconciliation by construction.
Multiplicative media-effect priors
The multiplicative model samples positive log-effect coefficients. The default is a LogNormal prior with median 0.1 and log-scale 0.7. A HalfNormal family is also supported. Parameters can be defined per media node or parent group. A group-level coefficient can receive centered node-level multiplicative deviations with a HalfNormal(0.35) local scale.
The coefficient is not a raw spend-to-outcome multiplier. It multiplies the fully transformed response and represents log-scale lift.
Fixed values and business-informed priors
Transform and effect parameters may be fixed where externally validated evidence exists. Otherwise, user inputs define prior centers and uncertainty, not immutable curves. Evidence source and validity period belong to the input contract and reporting metadata, while NUTS updates non-fixed parameters using the observed likelihood.
Bayesian inference engine
Naukr AI MMM uses NumPyro on JAX and samples the continuous posterior with the No-U-Turn Sampler (NUTS), an adaptive Hamiltonian Monte Carlo algorithm.
NUTS uses gradients of the log posterior to propose distant states efficiently, reducing the random-walk behavior of simpler samplers. Warm-up adapts the step size and mass matrix; retained draws then represent the posterior distribution.
Runtime controls
The low-level run_inference API defaults to:
- 500 warm-up iterations;
- 500 retained draws per chain;
- 2 chains;
- target acceptance probability 0.90;
- maximum tree depth 10;
- random seed 2026.
The orchestration layer has independent configurable defaults of 300 warm-up iterations, 300 draws, and 2 chains so candidate and final runs can be sized separately. Production deployments should set these deliberately.
The implementation uses NumPyro's default initialization behavior. It does not define a custom initializer. JAX performs automatic differentiation and JIT compilation on the active CPU, GPU, or TPU backend. Chains run in parallel when the local device count permits and sequentially otherwise.
Discrete choices such as additive versus multiplicative, adstock family, saturation family, baseline family, lag length, and neural-correction use are not sampled inside NUTS. They are represented as candidate specifications and compared using leakage-safe validation.
Likelihood and observation model
Additive likelihood
For observed cells,
The standardized observed outcome is modeled around the standardized expected outcome using a robust Student-t error distribution.
Terms: is the standardized observed outcome; is the standardized expected outcome; is degrees of freedom controlling tail heaviness; is the residual scale.
with
Residual scale receives a positive half-normal prior, while Student-t degrees of freedom are kept above two using an exponential prior.
Terms: is the residual scale; 0.5 is its prior scale; is Student-t degrees of freedom; is a positive offset; 0.1 is its exponential rate.
The Student-t likelihood is robust to occasional large residuals while keeping the conditional mean defined because .
Multiplicative likelihood
The ordinary multiplicative likelihood is
Positive observed outcome follows a log-normal distribution centered on expected log outcome, with positive log-scale noise.
Terms: is the observed positive outcome; is the expected log outcome; is log-scale residual noise; 0.25 is its prior scale.
An optional contaminated LogNormal likelihood mixes a regular component and a wider component. The default outlier probability is 0.05 and the default scale multiplier is 4. Component locations are adjusted so both components preserve the same response-scale conditional mean. This separates occasional heavy-tail noise from systematic media lift.
Only cells selected by the observation mask enter the likelihood.
Model diagnostics and validation
Sampling diagnostics
- R-hat compares within-chain and between-chain variation. Values near one indicate that chains mixed to a common stationary distribution. The default gate requires maximum R-hat no greater than 1.01.
- Effective sample size (ESS) estimates the number of independent-equivalent posterior draws after autocorrelation. The default minimum is 200.
- Divergences identify problematic HMC trajectories and posterior geometry. The gate requires zero divergences.
Weak sampler diagnostics are resolved back to media node, parent group, geography, or control labels when possible.
Predictive metrics
Given posterior-mean prediction over an evaluation mask:
RMSE is the square root of the average squared prediction error, so larger mistakes receive more weight.
Terms: is root mean squared error; is the prediction; is the actual outcome; is the number of evaluated observations; indexes observations.
MAE is average absolute error. WMAPE is total absolute error divided by total absolute actual outcome.
Terms: is mean absolute error; is weighted mean absolute percentage error; is absolute prediction error; is total absolute actual outcome.
R-squared equals one minus model squared error divided by the squared error from always predicting the observed average.
Terms: is the coefficient of determination; is the prediction; is the actual outcome; is the average actual outcome; indexes evaluated observations.
R-squared is not clipped, so it preserves its standard diagnostic meaning. The implementation reports overall point metrics, within-geography temporal fit after removing geography levels, and national aggregate time-series fit.
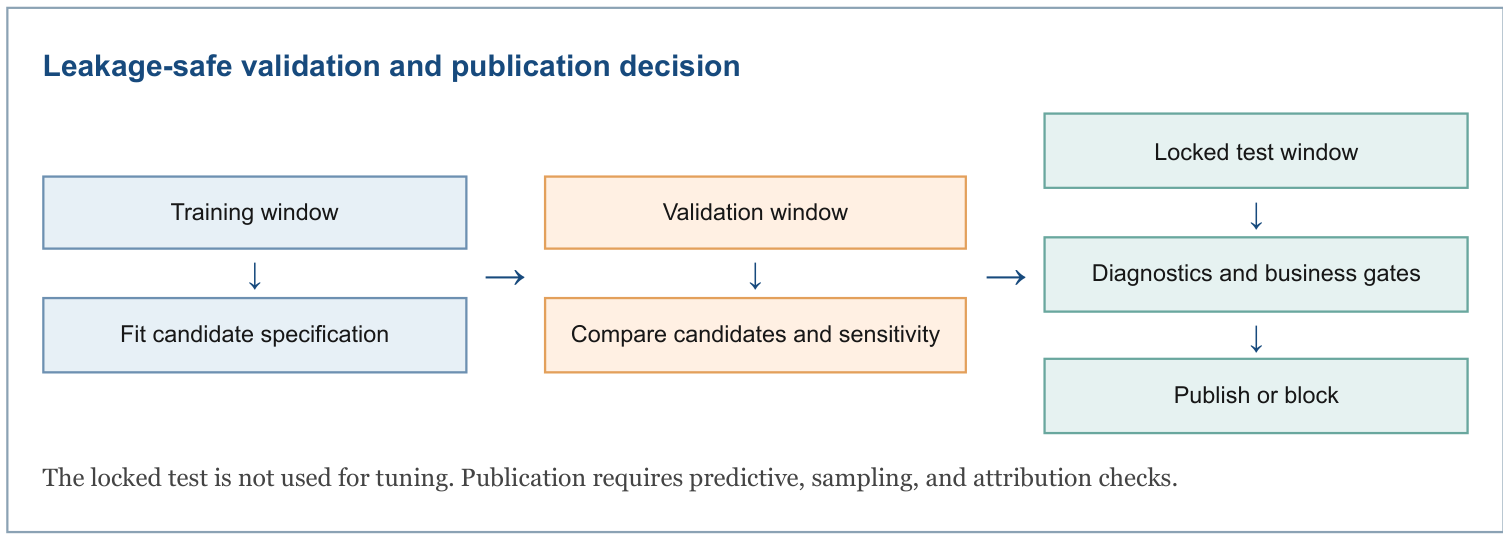
Posterior predictive interval diagnostics include empirical coverage and mean interval width. Validation-only interval calibration can add an absolute expansion learned from validation residuals; the locked test is never used to tune the interval.
Temporal validation
The pipeline supports:
- a chronological train, validation, and locked-test split;
- expanding-window rolling-origin folds;
- an optional balanced geography-time validation mask while preserving the final chronological test;
- simple leakage-safe forecast benchmarks;
- peak-capture diagnostics for material aggregate levels and changes;
- ROI reconciliation and prior-sensitivity checks.
Candidate specifications must pass configured acceptance gates before ranking. Accepted candidates are ranked primarily by validation WMAPE, followed by peak capture, temporal and national R-squared, overall R-squared, RMSE, interval width, and deterministic specification tie-breakers.
Attribution stability
The sensitivity run widens the active media prior and compares posterior mean profit-contribution shares. It reports maximum and mean absolute share changes. For additive models, ROI prior uncertainty is widened. For multiplicative models, the active log-effect prior is widened. This tests whether attribution depends excessively on one prior width.
Model identifiability and constraints
The implementation uses multiple complementary safeguards:
- Media execution is scaled by train-only typical exposure to improve geometry.
- Adstock, saturation, neural, and multiplicative-effect parameters are constrained to valid domains.
- Additive media effects are positive because ROI is log-parameterized.
- Multiplicative media coefficients are positive.
- Geography and media hierarchies share information through partial pooling.
- Centered hierarchy deviations prevent duplication of the global or group level.
- Adaptive pooling suppresses unsupported node-level deviations rather than silently treating them as independently identified.
- Collinearity and support diagnostics use pair correlations, VIF, activity, unique values, variation, and spend.
- The neural correction is monotone, concave, zero-anchored, normalized, and shrunk toward the parametric curve.
- Baseline changepoint and latent-trend bases are centered or orthogonalized against simpler trend terms.
- Train-only preprocessing and locked testing prevent leakage.
- Source-readiness checks require reviewed semantic roles, time-grain alignment, timestamp basis, and independent evidence where configured.
- Publication artifacts carry attribution status, pooling weight, prior versus posterior movement, and quality flags.
These mechanisms reduce unreasonable solutions but do not create information that is absent from the data. Strongly correlated or low-support media may only be interpretable at their parent-group level.
MMM: Results
Posterior media contributions
Every posterior draw produces a full time-by-geography-by-media contribution tensor.
Additive contribution
For draw ,
In each posterior draw, a node's contribution equals its sampled effect coefficient times its sampled transformed response.
Terms: is the media contribution in posterior draw ; is the sampled effect coefficient; is the sampled transformed response.
Business reporting may use an outcome multiplier when the modeled target and reported KPI differ:
Reported business contribution equals model contribution multiplied by the conversion factor from modeled outcome to business KPI.
Terms: is the business-scale contribution; is the outcome conversion multiplier; is the model-scale contribution.
Profit contribution is
Profit contribution equals incremental outcome contribution times profit or business value per outcome unit.
Terms: is the profit contribution; is profit or business value per modeled KPI unit; is the incremental outcome contribution.
The business value may vary by time and geography, so monthly or weekly margins and profit-per-transaction values are supported.
Multiplicative contribution
The implementation exports both channel-removal counterfactual contribution and conserving effect-share allocation as defined in the Models tab (see Additive versus multiplicative specification). Reporting artifacts label the basis so downstream users do not mix the two meanings.
Aggregation and decomposition
Posterior contributions can be aggregated by:
- time, including weekly, monthly, and yearly rollups;
- geography;
- media node;
- parent media group;
- portfolio total.
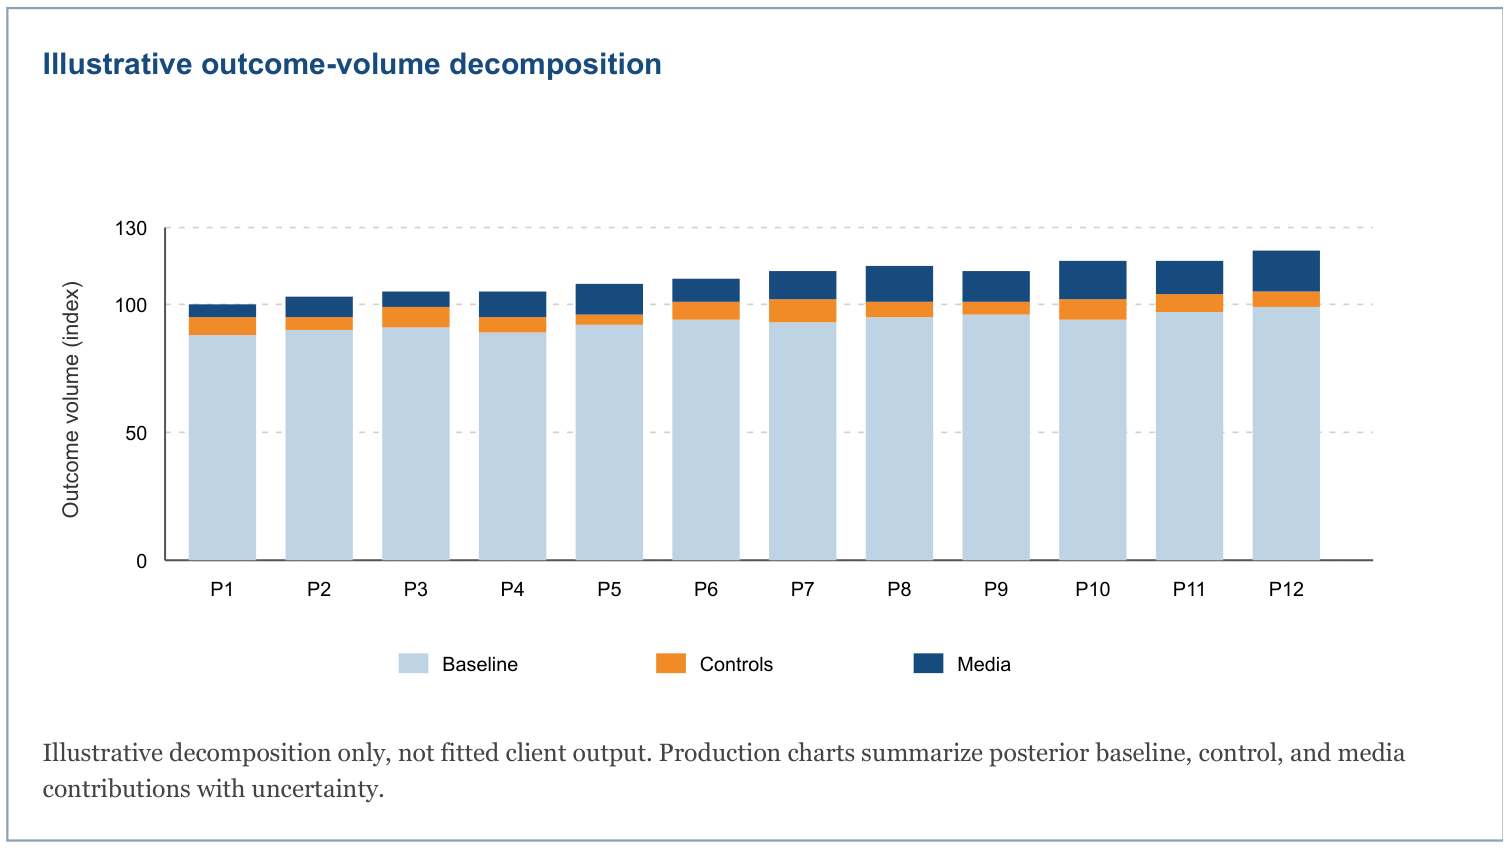
The decomposition separates base demand, controls, and media. Per-draw contribution percentage is
Contribution percentage equals a component's contribution divided by total predicted outcome, multiplied by 100.
Terms: is the selected component's contribution; is the total predicted outcome; identifies a posterior draw; multiplying by 100 converts the share to percent.
Summaries are computed after the nonlinear calculations and aggregation, which preserves posterior uncertainty correctly.
ROI and effectiveness metrics
General ROI
For reporting scope , such as a node, group, year, or portfolio,
ROI equals total incremental profit attributed to the selected scope divided by total media spend in that scope.
Terms: is ROI for scope in posterior draw ; is the incremental profit contribution; is media spend; defines the included times, geographies, and media nodes.
ROI is computed per posterior draw and then summarized. This is not generally equal to dividing two separately summarized quantities.
Outcome-specific interpretation
| Outcome | Implemented return interpretation |
|---|---|
| Volume | Incremental volume x unit margin / spend |
| Revenue | ROAS without margin; profit ROI with contribution margin |
| Profit | Incremental profit / spend |
| Conversions | Incremental conversions x profit per conversion / spend |
| Transactions | Incremental transactions x profit per transaction / spend |
| Transaction value | ROAS without margin; profit ROI with margin |
| Market share | Incremental share x market size x unit margin / spend, with percentage-point handling |
| Custom KPI | Incremental KPI x configured value per KPI unit / spend |
Effectiveness and efficiency
Incremental contribution describes effectiveness in outcome units. ROI combines that effectiveness with business value and spend efficiency. Raw coefficients should not be compared across media nodes without accounting for exposure scaling, transformation shape, and units.
The posterior contains media_beta draws for both model forms. In an additive model, that coefficient is derived from the sampled ROI and the fitting-period response denominator. In a multiplicative model, it is the sampled positive log-effect coefficient. The standard prior-diagnostic artifact reports the coefficient posterior for multiplicative models and the ROI posterior for additive models. The internal additive coefficient remains available in the posterior, but the standard business reports emphasize contribution and ROI, which are more comparable across differently scaled media nodes.
Response curves
The standard response-curve artifact is currently available for Weibull-CDF saturation. It evaluates the posterior curve on exposure multipliers from 0 to 3 times typical exposure, using 61 grid points by default, and reports mean, 5th, 50th, and 95th percentiles for response and curve parameters.
This artifact reconstructs the parametric Weibull-CDF saturation component. It does not apply the optional neural correction and should therefore be labeled as a parametric response-curve view when that correction is enabled.
The curve is a transformed-response curve used to understand diminishing returns and support later-stage planning decisions.
Uncertainty and posterior summaries
For a posterior-derived quantity , reports commonly include:
- posterior mean: ;
- posterior median: empirical 50th percentile;
- 90% credible interval: empirical 5th and 95th percentiles.
Uncertainty is propagated by calculating transformed response, predictions, counterfactuals, contributions, profit, and ROI separately for every posterior draw. This carries uncertainty from adstock, saturation, neural shape, baseline, controls, hierarchy, media effects, and observation noise into business outputs.
The posterior interval is a conditional Bayesian uncertainty statement under the selected model, priors, and supplied data. It is not a guarantee that model structure or source data are complete.